



Businesses today must release digital products quickly, reliably, and securely. Customers expect faster updates, employees need dependable systems, and leadership wants technology investments to deliver measurable business value.
This is where a strong DevOps strategy for business becomes important.
DevOps is not only a set of tools. It is a way to bring development, operations, security, and business teams together so that software and infrastructure can improve continuously. When DevOps is connected with cloud platforms, artificial intelligence, automation, and clear metrics, organizations can reduce delays and deliver better services faster.
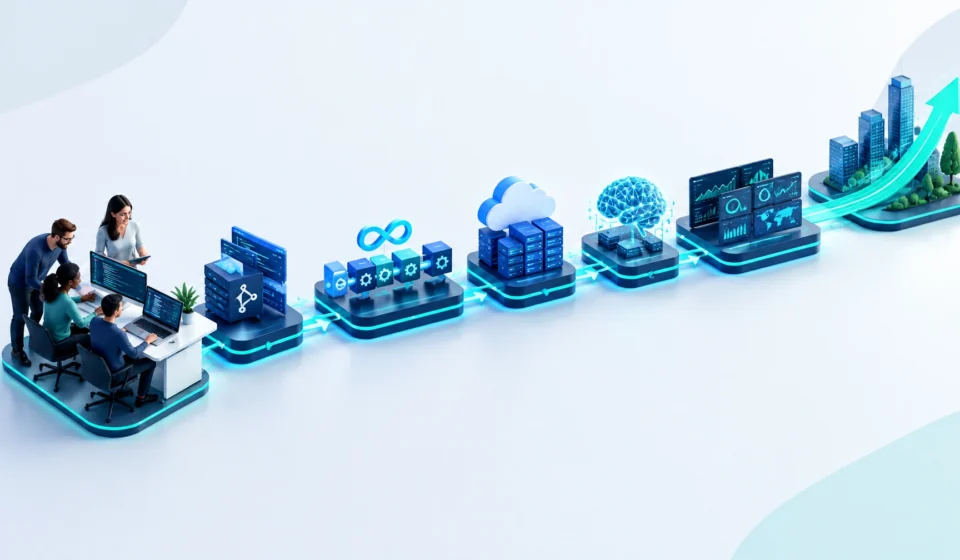
Below are five practical steps CIOs, CTOs, IT Heads, and DevOps Leads can use to build a faster and more reliable delivery model.
1. Create a culture of shared ownership
The first step is cultural, not technical.
Many organizations still operate through separate teams. Developers write code, testing teams validate it, operations teams deploy it, and security teams review it at the end. Every handoff creates a delay. When an issue appears, teams may spend more time assigning responsibility than solving the problem.
DevOps replaces this siloed model with shared ownership.
A cross-functional team should be responsible for the complete lifecycle of a service: from planning and coding to deployment, monitoring, security, and improvement. This does not mean every person must become an expert in every technology. It means teams must work toward the same business outcome.
Practical actions for leadership
- Create product or service teams that include development, QA, operations, and security.
- Give each team clear ownership of applications and services.
- Include reliability, security, and customer experience in team objectives.
- Encourage small, frequent releases instead of large and risky launches.
- Use blameless incident reviews to identify process and system improvements.
- Provide training in cloud, automation, cybersecurity, and AI-enabled tools.
Leadership support is essential. If performance reviews reward only new features, teams may ignore reliability and technical debt. A mature DevOps culture measures both delivery and operational health.
Microsoft’s documentation on how it delivers software with DevOps highlights autonomous teams, automated pipelines, production monitoring, and continuous learning as important principles.
The goal is simple: make the team responsible for delivering value, not just completing tasks.
2. Build a reliable CI/CD foundation
Continuous integration and continuous delivery: known as CI/CD: are the foundation of faster software delivery.
Continuous integration means developers merge code regularly and receive fast feedback from automated builds and tests. Continuous delivery ensures that validated software can be released safely through a repeatable process.
Without CI/CD, organizations often depend on manual testing, manual approvals, and release checklists. These processes may appear controlled, but they are slow and vulnerable to human error.

A practical CI/CD pipeline should include
- Source control for application code, configuration, and infrastructure definitions.
- Automated builds that create consistent and traceable artifacts.
- Automated testing, including unit, integration, API, security, and regression tests.
- Security checks such as dependency scanning, container scanning, and secret detection.
- Artifact management so the same tested artifact moves through environments.
- Progressive deployment using canary, blue-green, or feature-flag strategies.
- Rollback capability to restore a known-good version quickly.
Keep changes small and integrate them frequently. Smaller changes are easier to test, review, deploy, and recover from when something fails.
Your pipeline should also be the standard route to production. Manual changes made directly on servers create configuration drift and make audits more difficult. With pipeline-as-code, infrastructure-as-code, approvals, and audit trails, teams can move quickly while maintaining governance.
Useful CI/CD practices include building once and promoting the same artifact, using reusable pipeline templates, and keeping the main branch ready for release.
For regulated organizations, CI/CD can also support PCI, financial, insurance, and IT security audit requirements by maintaining evidence of who changed, tested, approved, and deployed each release.
3. Automate cloud infrastructure and use AI carefully
Automation is what allows DevOps to scale.
If a team must manually provision servers, configure networks, create databases, or prepare test environments, delivery will slow down as the organization grows. Manual work also creates inconsistency between development, testing, and production.
Infrastructure as Code (IaC) addresses this problem. Tools such as Terraform, Pulumi, CloudFormation, and Kubernetes manifests allow infrastructure to be defined in version-controlled files. Teams can review, test, reproduce, and roll back infrastructure changes just like application code.
Where automation can deliver value
- Provisioning AWS, Azure, or Google Cloud environments.
- Creating networks, security groups, load balancers, and databases.
- Configuring containers and Kubernetes clusters.
- Rotating secrets and certificates.
- Scaling infrastructure based on demand.
- Running compliance and configuration checks.
- Creating temporary development and testing environments.
- Decommissioning unused resources to reduce cloud costs.
AI can make this automation more intelligent. AI-enabled DevOps tools can help summarize incidents, identify unusual deployment patterns, recommend test cases, detect alert noise, and suggest likely causes during troubleshooting.
For example, an AI system may identify that a recent code change, database query, or infrastructure update is correlated with increased latency. It can help the operations team investigate faster: but it should not automatically make high-risk production changes without appropriate controls.
Governance matters
When using AI in DevOps:
- Protect source code, credentials, customer data, and intellectual property.
- Validate AI-generated scripts before execution.
- Keep human approval for high-risk infrastructure and production changes.
- Record AI-assisted decisions for audit and review.
- Use role-based access and least-privilege permissions.
- Test AI recommendations against operational and security policies.
AI should reduce repetitive work and improve decision-making. It should not become an uncontrolled path into production.
Organizations evaluating these capabilities may benefit from AI consulting services that connect AI use cases with cloud architecture, cybersecurity, data governance, and measurable business outcomes.

4. Implement observability, not just monitoring
Monitoring tells you that something may be wrong. Observability helps you understand why.
Modern applications often run across APIs, containers, databases, cloud services, networks, and third-party platforms. A single user request may pass through many components. Basic server monitoring cannot provide enough context to diagnose these environments quickly.
A modern observability program should bring together:
- Metrics: numerical measurements such as CPU usage, latency, error rate, throughput, and availability.
- Logs: detailed records of application, security, and infrastructure events.
- Traces: the path of a request across distributed services.
- Events: deployments, configuration changes, scaling activity, and incidents.
OpenTelemetry provides a vendor-neutral framework for generating, collecting, and exporting metrics, logs, and traces.
Teams should also define Service Level Objectives (SLOs). An SLO might require an application to achieve 99.9% availability or keep response time below a defined threshold. Error budgets help teams balance innovation and reliability. If the error budget is being consumed too quickly, the team may need to pause risky releases and focus on stability.
AI can support observability by identifying abnormal behavior, grouping related alerts, and recommending probable causes. However, AI-generated insights should be connected to reliable telemetry and reviewed by skilled engineers.
Observability must extend beyond applications. CIOs and IT Heads should consider cloud infrastructure, network performance, databases, virtualization platforms, data centers, and security controls. A service can appear healthy while the underlying power, cooling, storage, or network environment is approaching a critical condition.

5. Measure delivery performance and improve continuously
A DevOps strategy for business needs measurable results.
Without metrics, leadership may invest in new tools without knowing whether delivery is actually improving. Teams may also optimize the wrong things: for example, increasing deployment frequency while causing more incidents.
The DORA framework provides useful software delivery performance metrics. The current model includes:
- Change lead time: how long it takes for a change to move from version control to production.
- Deployment frequency: how often the team deploys.
- Change failure rate: the percentage of deployments requiring immediate intervention.
- Failed deployment recovery time: how long it takes to recover from a failed deployment.
- Deployment rework rate: the percentage of deployments caused by production incidents or unplanned remediation.
The DORA metrics guide explains how these measures can help teams understand throughput and instability.
Organizations can also track:
- Build and pipeline duration.
- Test failure and flakiness rates.
- Time spent waiting for approvals.
- Infrastructure provisioning time.
- Incident volume and severity.
- Cloud cost per application or business transaction.
- Customer satisfaction and application performance.
Metrics should support improvement: not punish teams. Do not compare very different applications or encourage teams to release unsafe changes simply to increase deployment frequency. Review metrics in context, discuss bottlenecks openly, and focus on progress over time.
A practical 90-day starting plan
Organizations do not need to transform everything at once. A focused pilot can create momentum.
Days 1–30: Assess
- Select one important application or service.
- Map the current delivery process.
- Identify manual handoffs and major bottlenecks.
- Establish baseline delivery and reliability metrics.
- Review security, compliance, and cloud dependencies.
Days 31–60: Automate
- Create or improve the CI pipeline.
- Add automated tests and security checks.
- Define infrastructure using code.
- Standardize deployment steps.
- Introduce logs, metrics, and traces.
Days 61–90: Improve
- Add progressive delivery or feature flags.
- Define SLOs and alerting policies.
- Test rollback and incident response.
- Use AI for selected, low-risk DevOps workflows.
- Review DORA metrics and plan the next improvement cycle.
Final thoughts
A successful DevOps strategy is a business capability, not just an engineering project. It connects people, processes, cloud infrastructure, automation, AI, security, and measurable outcomes.
Start with culture. Build a dependable CI/CD foundation. Automate infrastructure. Improve observability. Then use metrics to guide continuous improvement.
When these five steps work together, organizations can deliver software faster without sacrificing security, reliability, or governance.
Further reading
